Reading Flame Graphs in Go
I nvisible performance bugs are the ones that scale with you. A function that takes 800 nanoseconds at 100 rows and 130 microseconds at 10,000 rows looks fine in every test you write on day one, and quietly becomes the reason a page hangs on day three hundred. You cannot fix what you cannot see — and a guess is not seeing.
This is a walkthrough of making one such bug visible: write a benchmark, capture a CPU profile, and read the flame graph until the cost stops being a mystery. The example is a real lookup from PayMeter, a small Go payments service, but the workflow is the same for anything.
The lookup that lied#
PayMeter keeps an in-memory customer repository behind an interface. The first cut of “find a customer by email” did the obvious thing:
func (r *CustomerRepository) FindByEmail(_ context.Context, email string) (*customer.Customer, error) {
    r.mu.RLock()
    defer r.mu.RUnlock()
    for _, c := range r.byID {   // scan every customer
        if c.Email() == email {
            return c, nil
        }
    }
    return nil, customer.ErrNotFound
}
It passes every test. It reads cleanly. And it is O(n) — a full scan of the map on every call. At ten rows that is free. At ten thousand it is a scaling cliff hiding in plain sight.
Write the benchmark first#
Before touching the code, measure it. The trick that makes an O(n) bug jump out is a sub-benchmark sweep — run the same operation across input sizes so scaling shows up as a slope, not a single number.
func BenchmarkFindByEmail(b *testing.B) {
    for _, n := range []int{100, 1_000, 10_000} {
        repo, email := seedRepo(b, n)          // n customers; look up the last
        ctx := context.Background()
        b.Run(fmt.Sprintf("n=%d", n), func(b *testing.B) {
            b.ReportAllocs()
            b.ResetTimer()                     // exclude seeding from the timing
            for i := 0; i < b.N; i++ {
                repo.FindByEmail(ctx, email)
            }
        })
    }
}
Two lines earn their keep here: b.ResetTimer() throws away the fixture setup so you measure only the lookup, and b.ReportAllocs() surfaces allocations, which are usually the real story.
go test ./internal/infrastructure/memory -run='^$' -bench=FindByEmail -benchmem
BenchmarkFindByEmail/n=100        827.7 ns/op    0 allocs/op
BenchmarkFindByEmail/n=1000      9688   ns/op    0 allocs/op
BenchmarkFindByEmail/n=10000   129794   ns/op    0 allocs/op
Ten times the data, roughly ten times the time. That is O(n) written in numbers — and notice zero allocations the whole way, which tells you the cost is pure CPU, not the garbage collector. Now we know what is wrong. A flame graph will show us where.
-run='^$' matches no tests, so only benchmarks run. Add -count=10 and compare runs with benchstat when you need to prove a change is real and not noise.From numbers to a picture#
A CPU profile records where the program spends wall-clock CPU time. Any benchmark can emit one:
go test ./internal/infrastructure/memory -run='^$' -bench=FindByEmail -cpuprofile=cpu.prof
go tool pprof -http=: cpu.prof
-http=: starts a local web UI on a free port and opens your browser. The default view is a call graph; the one we want is under VIEW → Flame Graph.
Before reading the graph, two words that the whole thing is built on:
- flat — time spent inside a function itself.
- cum (cumulative) — that function plus everything it calls.
High cum with low flat means a function is just a caller; the cost is deeper. High flat is where work actually happens. That is your target.
How to read a flame graph#
The single rule: read it by width, not by height.
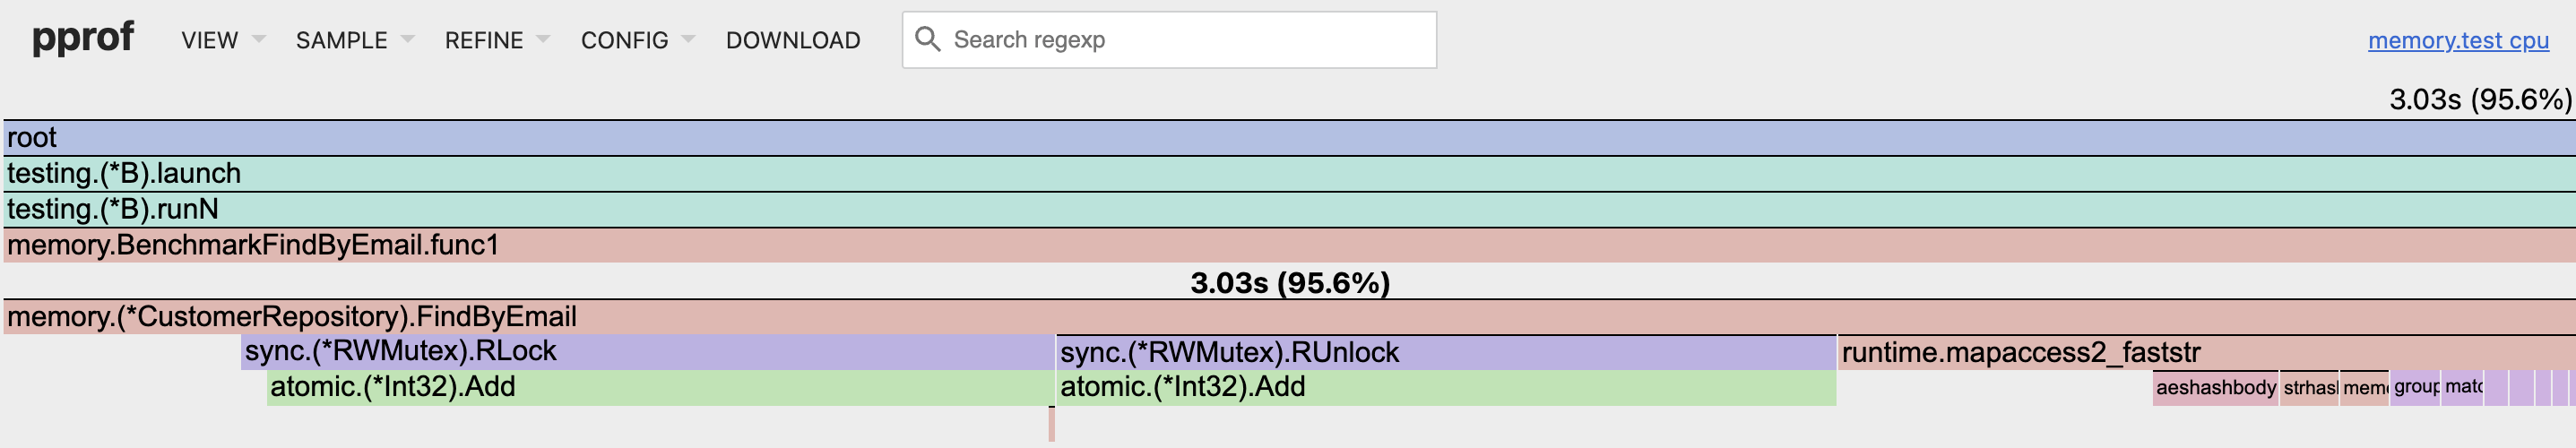
Everything below is the plumbing: root → testing.(*B).runN → BenchmarkFindByEmail → FindByEmail. Those bars are full-width because all the work happens inside the benchmark loop — expected. Then read what sits on top of FindByEmail:
runtime.mapaccess2_faststr— the map lookup itself.sync.(*RWMutex).RLock→atomic.(*Int32).Add— taking the read lock.sync.(*RWMutex).RUnlock→atomic.(*Int32).Add— releasing it.
The width grammar tells you three things at a glance:
- Width is inherited downward. A parent is as wide as its children plus its own self-time, so a wide box always has a wide culprit somewhere above it. Keep climbing until the width stops shrinking.
- The hot spot is a wide box near the top — a wide leaf is a function burning time itself, not delegating.
- Tall-and-thin is cheap. A deep stack a few pixels wide cost almost nothing, regardless of how many frames it has.
Colors are meaningless — warmth is just visual separation (hence “flame” or “torch”). Only width is data.
The interesting read here is not a bug — it is a lesson. RLock, RUnlock, and the map access each take roughly a third of the width, which means the two lock operations together now cost about twice the lookup they were guarding. Once the O(n) scan was gone, the mutex atomics became the dominant cost. Fix the big thing and the next thing down becomes visible. That is the normal shape of an optimized function, not a problem to chase.
Zooming into a single map lookup#
Click runtime.mapaccess2_faststr and the graph zooms to the anatomy of one Go map probe on a string key.
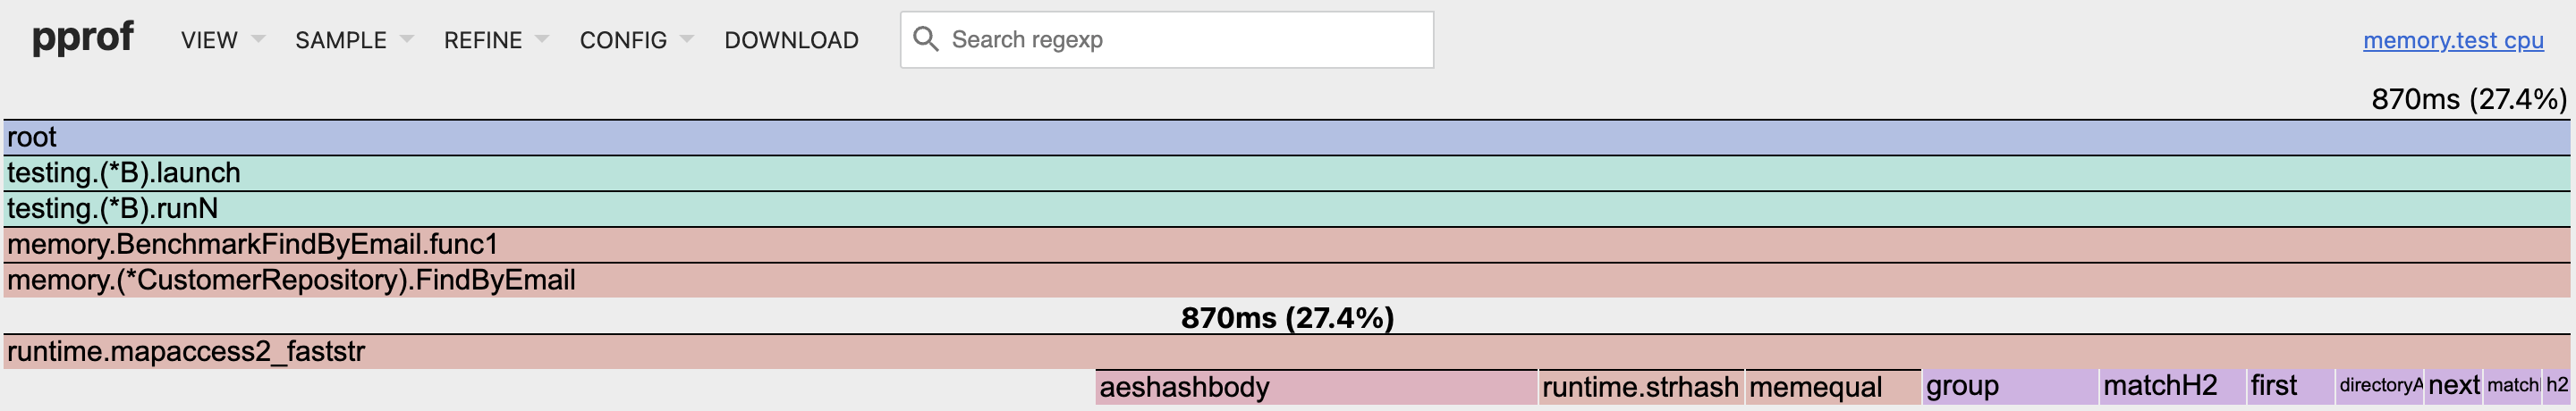
The header now reads its share of the total profile — here, 27.4%. Reading the leaves widest-first:
aeshashbody/runtime.strhash— hashing the email string using the CPU’s AES instructions. The single biggest slice.memequal— byte-compare the actual key to rule out a hash collision.group,matchH2,first,h2— Swiss-table bookkeeping: pick the group, match the hash’s tag byte against a bank of slots at once.
There is a real insight buried in those box widths:
That is the deep reason the fixed FindByEmail is O(1) in customer count: the graph is all hash, match, one compare, with no iteration anywhere. Whether the map holds a hundred entries or ten thousand, you hash one email and probe one group. It is why the three sub-benchmarks collapsed onto the same number after the fix.
The fix, and the proof#
The fix is boring, which is the point — keep an email index alongside the id map and maintain it in Save and Delete:
func (r *CustomerRepository) FindByEmail(_ context.Context, email string) (*customer.Customer, error) {
    r.mu.RLock()
    defer r.mu.RUnlock()
    c, ok := r.byEmail[email]   // one probe, no scan
    if !ok {
        return nil, customer.ErrNotFound
    }
    return c, nil
}
Re-run the exact same benchmark:
BenchmarkFindByEmail/n=100      34.12 ns/op    0 allocs/op
BenchmarkFindByEmail/n=1000     31.88 ns/op    0 allocs/op
BenchmarkFindByEmail/n=10000    31.79 ns/op    0 allocs/op
Flat ~32 ns regardless of size — O(1). At ten thousand customers that is roughly a 4000× speedup, and the slope is gone. The flame graph is the confirmation: no scan tower, just a hash and a lock.
Knowing when to stop#
The zoomed graph also tells you something a lot of profiling advice leaves out: when to stop. Inside mapaccess2_faststr there is nothing to fix. It is hardware-accelerated hashing and SIMD slot matching — the Go runtime doing its job about as well as a general-purpose map can. The only way to beat it would be to not hash a string at all, which is an absurd trade for a lookup already at 32 nanoseconds.
Premature optimization is the root of all evil.
A profile is not a to-do list of everything that costs time. It is a map of where cost concentrates, so you can spend your effort on the one box that matters and leave the irreducible ones alone. The discipline is reading the graph and then having the judgment to close the tab.
Do it yourself#
The whole loop, against any Go code:
- Benchmark the suspect function, sweeping input sizes with
b.Run. - Profile it:
go test -bench=X -cpuprofile=cpu.prof. - Open the flame graph:
go tool pprof -http=: cpu.prof→ VIEW → Flame Graph. - Read wide — find the widest leaf, climb to the widest box you own.
- Fix, then re-benchmark to prove the delta is real.
The benchmarks, the fix, and a full profiling guide live in the PayMeter repo — see docs/profiling.md and the make bench-cpu / make pprof-cpu targets, which wrap the commands above.
| Reading a flame graph | What it means |
|---|---|
| Wide box | Large share of the resource (CPU time, bytes) |
| Height | Call depth only — not time, not slowness |
| Wide leaf on top | The hot spot — work happening here, optimize it |
| Tall and thin | Cheap — ignore it |
| Color | Meaningless — visual separation only |
high cum, low flat |
Just a caller — look higher up the stack |